

Key Takeaways
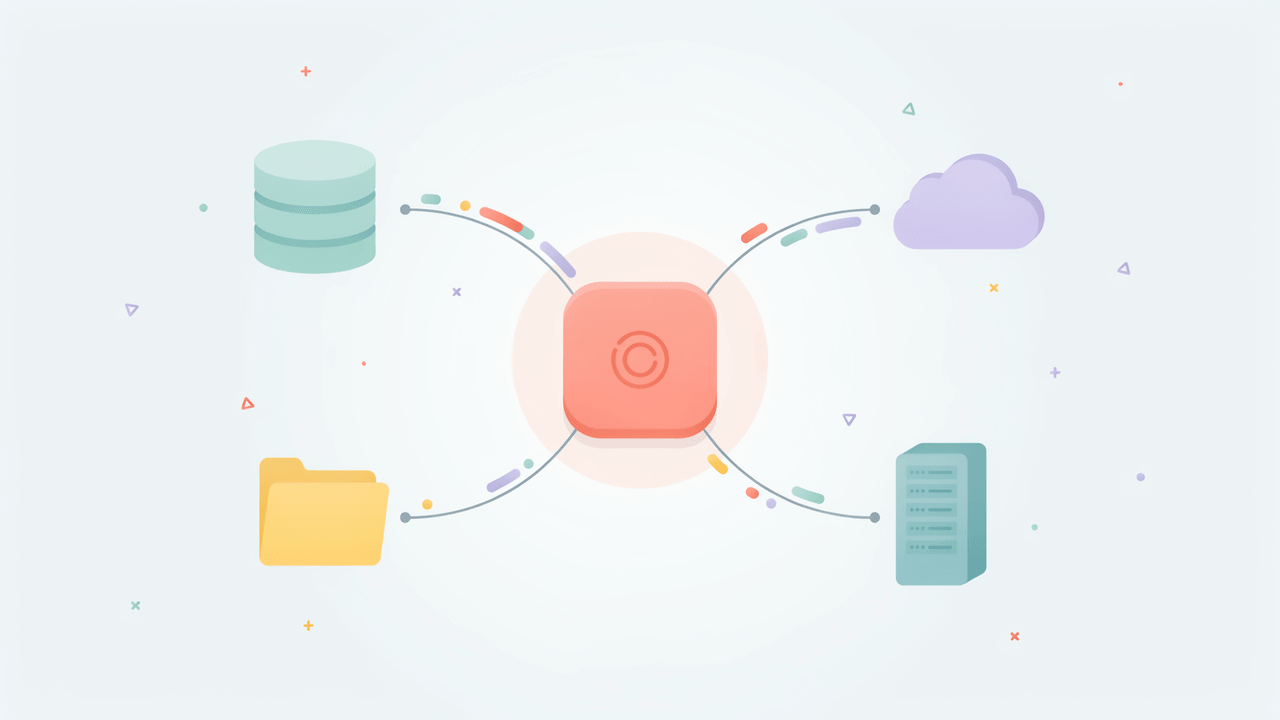
- A unified data management platform holds the authoritative version of operational data (products, customers, suppliers, assets, reference data) in one governed model. It syncs it to every system that needs it. Analytics platforms consume this data. They don't replace it.
- AI raised the price of bad data. Gartner expects organizations to abandon 60% of AI projects that lack AI-ready data through 2026.
- The EU Data Act turned data export and provider switching into legal obligations for cloud and SaaS vendors. Lock-in is now a procurement and compliance topic.
- Most failed projects fail on ownership and scope. Unclear attribute owners and big-bang migrations cause more damage than missing features.
- Test any platform with your messiest real data and a full export before you sign.
What A Unified Data Management Platform Actually Unifies
The term gets stretched. Vendors attach it to data warehouses, lakehouses, MDM suites and integration hubs. This article uses the operational meaning: one platform where an organization defines its core entities, stores the correct version of each record, checks its quality and distributes it to ERP, ecommerce, CRM, marketplaces and partner portals.
A typical scope covers master data for products, customers, suppliers and locations. It adds product information with channel-specific attributes, digital assets linked to the records they describe, and reference data such as units of measure, country codes and classification systems like ETIM, ECLASS, UNSPSC or GS1 GPC. On top sits an integration layer (import feeds, export feeds, APIs, scheduled sync) and governance: roles, field-level permissions, workflows, and a full change history.
The analytical stack sits downstream. A lakehouse answers what happened last quarter. A unified data management platform answers what the correct weight of item 4711 is right now and who changed it on Tuesday. Companies that confuse the two often build an excellent warehouse and still ship three conflicting product descriptions to three channels. The data was never fixed at the source.
Why 2026 Changed The Requirements
AI Turned Data Quality Into A Budget Line
A Gartner survey found that 63% of organizations either lack the right data management practices for AI or don't know whether they have them. Based on this, Gartner predicts that organizations will abandon 60% of AI projects unsupported by AI-ready data through 2026. Gartner also states that traditional data management is too slow and too rigid for AI teams, that data often sits in silos across many systems, and that most organizations lack the metadata to judge whether their data is ready at all. Its recommendation is to move metadata from passive documentation to active, automated use.
"If the data has issues, then the data is not ready for AI." Gartner, 2025
In practice, AI needs context for every record: the source, the last change, the validation status, and the completeness per channel. A platform that stores this as queryable metadata gives an AI pipeline a simple filter. Only records that passed validation go into training sets or retrieval indexes. Without that metadata, every AI project rebuilds the same filter by hand. And then the next project does it again.
Agents Write Data Back
The first wave of AI read data. Agents change the direction of flow. An agent that enriches product descriptions, maps supplier attributes, or fixes missing units writes into master data. That makes access control a data platform question.
Gartner predicts that over 40% of agentic AI projects will be canceled by the end of 2027, citing escalating costs, unclear business value, and inadequate risk controls. The same release notes that integrating agents into legacy systems is technically complex and often requires costly modifications.
The risk controls an agent needs are mostly ordinary data platform features. Machine users need their own roles. Write rights should be limited to specific fields. Every change needs a version and a way to roll it back. Generated values should carry a flag so reviewers and downstream systems know where they came from, and a review workflow should sit between the agent and publication. If the platform can't do this, the choice narrows to full write access or none. Full access fails the risk review. No access ends the use case.
The EU Data Act Made Portability Enforceable
The Data Act applies since 12 September 2025. Two parts matter for anyone buying or running a unified data management platform.
First, providers of data processing services must remove obstacles to switching. SaaS and PaaS providers must offer open interfaces and, at minimum, export customer data in a commonly used, machine-readable format. Switching charges, including data egress fees, disappear completely from 12 January 2027. Exit terms in platform contracts are now something buyers can and should negotiate in detail.
Second, manufacturers of connected products become data holders. They must tell users which data a product generates, in what volume and at what collection frequency, and the scope includes relevant metadata. This information belongs to the product. It sits naturally next to dimensions, certifications, spare part lists and warranty terms in the product master record. Companies that keep it in a separate legal spreadsheet end up with two versions after the first product revision.
The Data Act also sets safeguards against unlawful access by non-EU government bodies to non-personal data held in the EU. For some industries, this moves hosting location and self-hosting options from IT preference to selection criterion.
The Risks That Show Up In Real Projects
Feature gaps rarely kill a unified data management project. The following problems do, and most of them are visible before the contract is signed.
A Data Model The Vendor Owns
Many suites ship a fixed schema with extension points. That works until the business changes. A manufacturer adds a service business and needs contracts linked to installed units. A regulation adds sustainability fields. If each change needs a vendor release or custom code that breaks on upgrade, the platform slowly becomes the next legacy system.
The test is simple. Ask the vendor to add a new entity with relations to two existing ones, during the demo, through configuration only. Then ask how that change survives the next upgrade.
The Big-Bang Migration
Projects that try to move every domain at once tend to stall in the data mapping phase. Each source system has its own interpretation of "product," "variant," or "customer," and resolving all of them in parallel overloads the few people who understand the data. A domain-by-domain rollout ships value sooner and exposes modeling mistakes while they are cheap to fix.
Nobody Owns The Attribute
A platform can enforce rules. It can't decide who is responsible for the net weight, the hazard classification, the customs tariff number, or the marketing description. When ownership stays vague, people fix data in whichever system is open on their screen, and the platform turns into one more copy. Assign an owner per attribute group, record it in the platform, and route validation failures to that person.
A unified data management platform centralizes responsibility. If responsibility stays scattered, the data will follow it.
Integration Sprawl
Point-to-point integrations grow quadratically. Eight systems connected directly need up to 28 interfaces. The same eight systems connected through a central platform need eight. The arithmetic is obvious, but many companies still add a direct ERP to shop connection "just for prices" and end up with a hidden second source of truth. Decide per attribute which system leads, and route everything else through the platform.
Pricing That Punishes Growth
Some pricing models scale with records, SKUs, channels, or API calls. The costs look fine at go-live and grow with every new product line or market. Model the price for three years of expected growth before signing, including the cost of the extra environments you will need for testing.
AI-Generated Content Without Provenance
Generated descriptions and attribute values can enter golden records quickly and quietly. Six months later, nobody knows which values a person checked. Store provenance per value, at least "manual," "imported," "translated" and "generated," and keep generated values out of regulated fields such as safety data until someone approves them.
Architecture Choices And Their Trade-Offs
There is no single correct architecture. Each option shifts effort to a different place.
A central hub stores and authors data in one place and pushes it out. It gives the clearest ownership and the simplest audit trail. The cost is migration effort and the need to agree on one model across departments.
A coexistence model lets source systems keep authoring some attributes while the platform consolidates, enriches, and redistributes them. ERP keeps prices and stock; the platform owns marketing content and classification. This is the most common pattern in manufacturing because it doesn't require replacing ERP processes. It needs precise rules about which system leads for each attribute, or two systems will overwrite each other.
A data fabric leaves data in its sources and provides a virtual, unified view on top. It's fast to start and works well for read access and analytics. It is weak for authoring and quality enforcement, because there is no central place where a record gets corrected.
A data mesh assigns data ownership to business domains that publish data as products. It scales ownership well in large organizations with mature teams. In mid-sized companies, it often stalls because the domains lack the people to run their own data products.
Many organizations combine these. A coexistence hub for master data with a fabric for analytical access is a common and workable setup.
How To Evaluate A Unified Data Management Platform
Demos use clean sample data. Your evaluation should not. Run a proof of concept with a real export from your messiest source and check the following:
- Model changes through configuration.
Add an entity, a relation and a set of attributes without code, then confirm the change survives an upgrade. - Full export.
Export all records, assets, relations and change history in an open format. Under the Data Act, this is the minimum, so ask how it works in practice and how long it takes. - API coverage.
Every object and action available in the user interface should be available through the API, including configuration metadata. - Field-level permissions and machine users.
Create a restricted role for an AI agent or integration and confirm it can write only the intended fields. - Validation and completeness rules.
Define channel-specific completeness and check that failed records get blocked from export, with a clear reason. - History and rollback.
Change a value, find out who changed it and from which source, then restore the previous version. - Hosting and licensing options.
Clarify hosting regions and self-hosting options. Ask what happens to your data and configuration if the contract ends.
Score the gaps by effort to close, not by count. One missing export path can outweigh ten missing convenience features.
Where A Configurable Open-Source Platform Fits
Configurable, open-source platforms address the data model and lock-in risks directly, because the customer controls both the configuration and the code. AtroCore is one example. It is licensed under GPLv3, lets administrators create entities and relations from the admin panel, exposes a REST API, and supports import and export for any entity, including newly created ones. Product information management and digital asset management run as modules in the same instance, so products, assets, and other master data share one model.
Our customers turn to us with a familiar starting point. A manufacturer keeps technical product data in ERP, marketing texts in spreadsheets, images on a file server and classification data in yet another tool. Every catalog update means collecting data by hand and checking it by email. In these projects, we set up a coexistence model: ERP stays the leading system for prices, stock, delivery times, and order-relevant fields, while AtroCore becomes the leading system for descriptions, classification, assets, and channel-specific attributes. Exports to shops and partners run from validated records. The practical change is that a missing attribute shows up as a failed rule on a dashboard before a customer finds it in a catalog.
In projects we implemented for equipment manufacturers, the Data Act information requirements became regular product attributes: data types generated, expected volume, collection frequency, and the access method. Product managers maintain them in the same record as technical specifications, and a validation rule blocks publication of a connected product while those fields are empty. Legal review happens on one record, and the information reaches the product page and the documentation from the same source.
Open source shifts some work to you. Someone has to own the configuration and plan upgrades. Companies without an internal data owner usually need an implementation partner or the vendor's support. The benefit is that the platform adapts to the business model, and the exit path is open by design.
A Rollout Sequence That Holds Up
Start with one domain that has visible pain and a clear owner. Product data in manufacturing and supplier data in procurement are typical candidates. Map which system leads for each attribute before configuring anything, because this document resolves more disputes than any feature.
Connect the leading source systems first, then the consuming channels. Put validation rules in place before the first export, so bad data never reaches a customer through the new platform. Add AI enrichment only after provenance flags and review workflows work, and give the agent its own restricted role from day one.
Expand to the next domain once the first one runs without manual workarounds for a full release cycle. That is the signal the model, the ownership, and the integrations hold. Each new domain then reuses the same governance, which is where a unified data management platform starts paying back the effort.